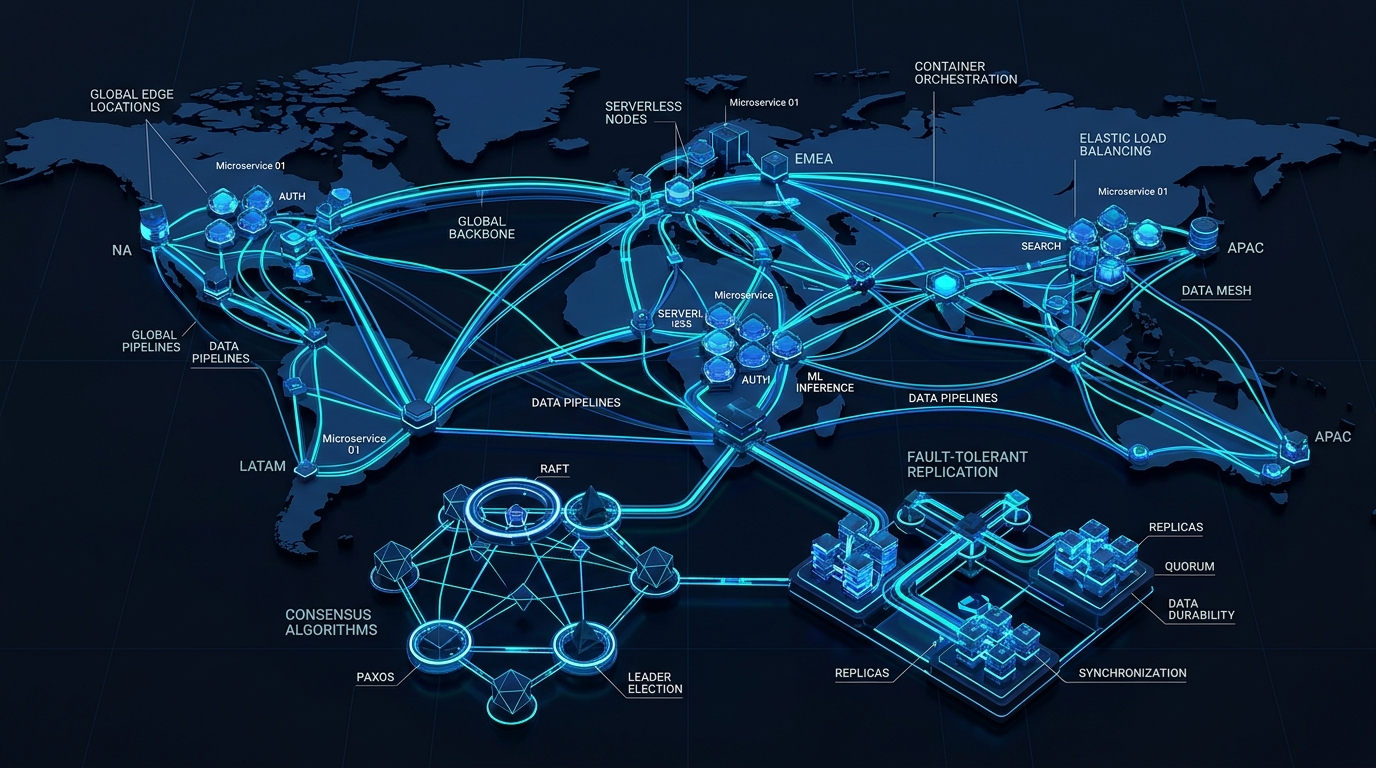
At 100,000 queries per second, textbook database patterns break down. We explore how modern distributed infrastructure handles network partitions, split-brain hazards, and asynchronous replication while guaranteeing event-driven consistency across geographic regions.
Every software architecture looks elegant in architecture diagrams and unit tests. But when production volume scales past tens of thousands of concurrent writes across geographically dispersed nodes, subtle fallacies of distributed computing immediately surface: networks drop packets, clocks drift, and hardware caches invalidate unpredictably.
Under extreme load, naive synchronization primitives like distributed locks and two-phase commits (2PC) quickly degrade into severe bottlenecks. A single slow database replica or transient TCP timeout can block thousands of threads, causing cascading thread pool exhaustion across upstream microservices.
To achieve true multi-region high availability without risking split-brain data corruption, modern enterprise engineering must move from synchronous transactions toward asynchronous consensus topologies. Modern consensus algorithms such as Raft and Multi-Paxos provide deterministic state machine replication, yet applying them directly to user-facing write paths introduces unacceptable latency penalties.
At Intactic, we decouple the write acknowledgment path from cross-datacenter consensus by leveraging transactional outbox pipelines. By capturing mutations into immutable append-only event logs, local nodes acknowledge client requests within sub-millisecond envelopes while distributed workers asynchronously reconcile multi-entity state using idempotent compensating sagas.
Wall-clock time in distributed computing is inherently unreliable due to NTP skew and leap-second adjustments. Relying on physical server timestamps for conflict resolution routinely causes silent data overwrites in high-concurrency environments. Hybrid Logical Clocks (HLC) solve this fundamental dilemma by combining physical monotonic clock readings with Lamport logical counters. This allows distributed nodes to establish strict causal ordering without requiring specialized atomic clocks or GPS synchronization hardware.
True architectural resilience requires designing systems that expect partial failure as the standard operating state. By deploying automated circuit breakers, exponential backoff with full jitter, and deterministic bulkhead thread pooling, mission-critical platforms absorb downstream outages without dragging down customer-facing availability.